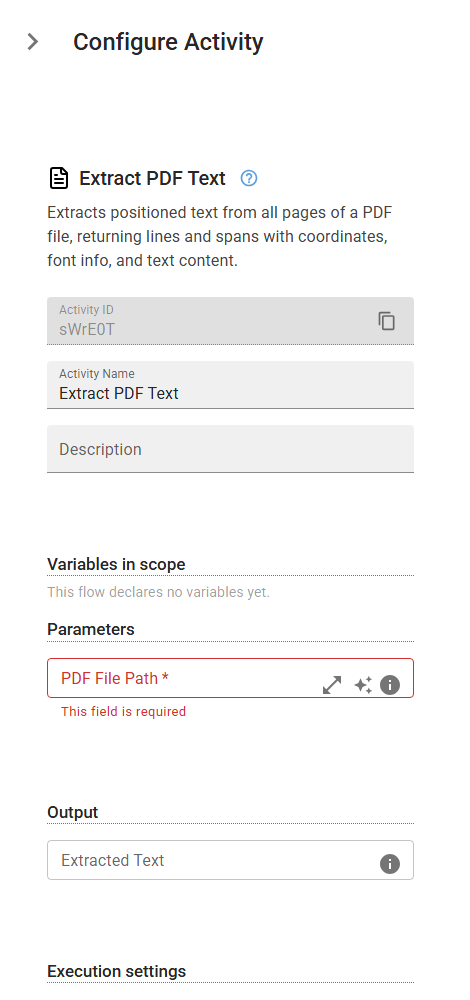
Extract PDF Text
Extracts positioned text from all pages of a PDF file, returning lines and spans with coordinates, font info, and text content.
Category: Structured Data Files (Excel, JSON, PDF) · Group: Files · Activity name: ExtractPDFText
Example
outputVariable = ExtractPDFText("<filePath>")
Inputs
| Name | Type | Required | Default | Description |
|---|---|---|---|---|
| PDF File Path | string | Yes | Path to the PDF file to extract text from. |
Outputs
| Name | Type | Description |
|---|---|---|
| outputVariable | json | JSON object with extracted text data: - numPages: Total number of pages - pages: Array of page objects, each containing: - index: Page number (0-based) - lines: Array of { y, text } — full text lines - spans: Array of { x, y, endX, fontSize, font, text } — positioned text spans Access fields using: {{pdfText["pages"][0]["lines"][0]["text"]}} to get the first line of the first page. |